
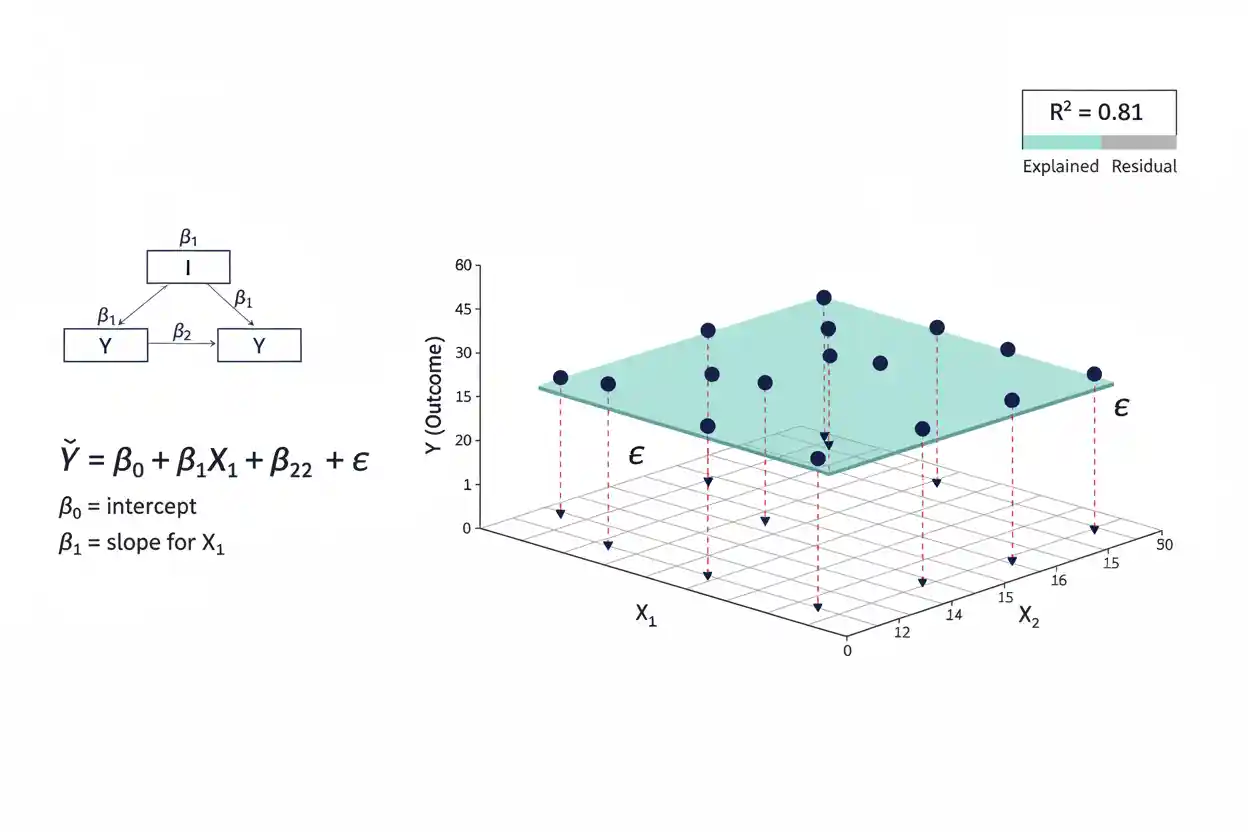
Multiple Regression: Definition, Formula & Example

Multiple regression is a statistical method used to model a quantitative outcome as a function of two or more predictors. It extends the basic idea of fitting a relationship between an outcome and a single explanatory variable by allowing several predictors to contribute simultaneously to the fitted value. This makes the method useful when an outcome such as sales, income, test performance, production cost, demand, or measurement response may be related to several characteristics at once. Each regression coefficient describes the estimated change in the outcome associated with a one-unit change in its predictor while the other predictors included in the model are held constant. That conditional interpretation is one of the defining features of multiple regression and is also one of the most commonly misunderstood.
A fitted model can be used for description, prediction, adjustment, and certain inferential questions, but none of those purposes automatically establishes causation. Model quality depends on more than a high R²: functional form, residual behavior, influential observations, multicollinearity, sampling structure, uncertainty, and out-of-sample performance can all matter. Multiple regression therefore provides a powerful framework for quantitative analysis when its coefficients, assumptions, and limitations are interpreted together rather than treating the fitted equation as a complete description of the underlying process.
Multiple regression sits within Statistics & Probability and is a core method in Inference & Regression. It shares the general regression idea with logistic regression, but the standard multiple linear regression model considered here is designed for a quantitative response rather than a binary outcome.
What Is Multiple Regression?
Multiple regression models the expected value of a quantitative response Y using several predictors X₁, X₂, …, Xₖ. In its standard linear form, the population model is:
Y = β₀ + β₁X₁ + β₂X₂ + … + βₖXₖ + ε
where β₀ is the intercept, β₁ through βₖ are population regression coefficients, and ε represents the part of Y not explained by the linear predictor.
The corresponding fitted sample equation is:
ŷ = b₀ + b₁x₁ + b₂x₂ + … + bₖxₖ
Here, ŷ is the predicted response and b₀, b₁, …, bₖ are estimates calculated from the sample data.
The distinction between β and b is useful. The β values are population parameters that are generally unknown. The b values are sample statistics used to estimate them.
Multiple regression therefore uses observed data to estimate a conditional relationship between an outcome and several predictors simultaneously.
Multiple Regression Formula
For k predictors, the fitted equation is:
ŷ = b₀ + Σbⱼxⱼ
or, written explicitly:
ŷ = b₀ + b₁x₁ + b₂x₂ + … + bₖxₖ
Suppose a fitted model predicting monthly sales is:
ŷ = 25 + 3x₁ + 1.5x₂
where x₁ represents advertising expenditure in specified units and x₂ represents the number of sales representatives.
For:
x₁ = 10
and:
x₂ = 8
the predicted response is:
ŷ = 25 + 3(10) + 1.5(8)
ŷ = 25 + 30 + 12
ŷ = 67
The fitted model predicts a response of 67 units for that combination of predictor values.
The equation provides the predicted conditional mean according to the fitted linear model. It does not guarantee that an individual observation will equal 67 because actual observations also contain residual variation.
What Does a Regression Coefficient Mean?
In multiple regression, each slope coefficient has a conditional interpretation.
Consider:
ŷ = 25 + 3x₁ + 1.5x₂
The coefficient:
b₁ = 3
means that a one-unit increase in x₁ is associated with an estimated increase of 3 response units when x₂ is held constant.
Similarly:
b₂ = 1.5
means that a one-unit increase in x₂ is associated with an estimated increase of 1.5 response units when x₁ is held constant.
The phrase “holding the other included predictors constant” is essential. Multiple regression coefficients do not generally describe the same relationship that would be obtained by examining each predictor separately.
A predictor may have a strong unadjusted relationship with Y yet a much smaller coefficient after other related predictors are included. The opposite can also occur.
The Intercept
The intercept b₀ is the fitted value of Y when every numerical predictor equals zero and every categorical predictor is at its reference level.
In:
ŷ = 25 + 3x₁ + 1.5x₂
the intercept is:
b₀ = 25
so the model predicts:
ŷ = 25
when:
x₁ = 0
and:
x₂ = 0
Whether this value has substantive meaning depends on the context. If zero is a realistic value for both predictors, the intercept may be directly interpretable. If the observed data contain no values remotely near zero, the intercept may be mathematically necessary without being practically meaningful.
An intercept should therefore not be given a substantive interpretation simply because it appears in the equation.
Residuals
A residual is the difference between an observed response and its fitted value:
eᵢ = yᵢ − ŷᵢ
Suppose an observation has:
y = 72
while the model predicts:
ŷ = 67
Then:
e = 72 − 67
e = 5
The model underpredicted the observation by 5 units.
If instead:
y = 63
then:
e = 63 − 67
e = −4
The model overpredicted the observation by 4 units.
Residuals are central to multiple regression because they reveal what remains after the fitted linear predictor has been applied. Their size and pattern help analysts evaluate whether the model provides a reasonable representation of the data.
How Ordinary Least Squares Fits the Model
The most common form of multiple linear regression uses ordinary least squares, or OLS, to estimate the coefficients.
OLS chooses coefficient estimates that minimize the sum of squared residuals:
SSE = Σ(yᵢ − ŷᵢ)²
Equivalently:
SSE = Σ[yᵢ − (b₀ + b₁x₁ᵢ + … + bₖxₖᵢ)]²
The squared residuals ensure that positive and negative prediction errors do not cancel one another and place greater numerical weight on larger errors.
The fitted coefficients are those that produce the smallest possible SSE among the linear models available under the specified set of predictors.
This explains why changing the set of predictors can change every coefficient: the entire collection of coefficients is estimated jointly to minimize the model’s residual sum of squares.
Worked Multiple Regression Example
Suppose a company models weekly sales using advertising expenditure and store traffic. The fitted regression equation is:
ŷ = 12 + 2.4x₁ + 0.05x₂
where:
- x₁ = advertising expenditure in hundreds of currency units
- x₂ = number of store visitors
- ŷ = predicted weekly sales in specified units
For a store with:
x₁ = 5
and:
x₂ = 300
the prediction is:
ŷ = 12 + 2.4(5) + 0.05(300)
ŷ = 12 + 12 + 15
ŷ = 39
The predicted weekly sales value is 39.
Now consider the coefficient for advertising:
b₁ = 2.4
Conditional on store traffic remaining fixed, one additional unit of x₁—meaning an additional hundred units of advertising expenditure under this coding—is associated with an estimated 2.4-unit increase in weekly sales.
The coefficient for traffic is:
b₂ = 0.05
Holding advertising fixed, one additional visitor is associated with an estimated increase of 0.05 sales units according to the fitted model.
These interpretations describe conditional associations within the specified regression model. They are not automatically causal effects.
Why Multiple Regression Is Useful
Many real outcomes are related to more than one observable factor. A model of housing prices might use floor area, location characteristics, property age, and number of bedrooms. A model of production costs might use output volume, labor hours, energy consumption, and material prices. A model of academic performance might incorporate prior scores, attendance, study time, and other characteristics.
Analyzing only one predictor at a time can overlook how predictors overlap.
Multiple regression allows those predictors to enter the same model, making it possible to estimate the relationship associated with one predictor conditional on the others.
This adjustment can be useful, but it should not be confused with automatically eliminating every alternative explanation. Regression can only condition on variables that are represented appropriately in the model and supported by the data.
Continuous Predictors
A continuous predictor typically enters the basic model as:
bⱼxⱼ
The coefficient bⱼ then represents the estimated difference in the response associated with a one-unit increase in xⱼ, holding the other included predictors constant.
Suppose:
b₁ = −4.2
for a variable measuring product price in dollars.
The interpretation is that a one-dollar increase in price is associated with an estimated 4.2-unit decrease in the response, conditional on the other predictors.
If one unit is too small to be meaningful, the coefficient can be rescaled.
For a ten-unit change:
Change in ŷ = 10b₁
So:
10(−4.2) = −42
A ten-dollar increase corresponds to an estimated 42-unit decrease under the same linear relationship.
Categorical Predictors
Categorical predictors can be included through indicator variables.
Suppose a predictor has three regions:
- North
- South
- West
If North is chosen as the reference category, create indicators for South and West.
A model might be:
ŷ = b₀ + b₁x + b₂ISouth + b₃IWest
where:
ISouth = 1 for South, otherwise 0
and:
IWest = 1 for West, otherwise 0
Then b₂ represents the estimated difference between South and North, holding x constant.
Similarly, b₃ represents the estimated difference between West and North.
The reference category is incorporated through the intercept and does not receive its own separate indicator when an intercept is present.
Changing the Reference Category
Changing the reference category alters the numerical coefficient representation but does not change the fitted values of an otherwise equivalent model.
Suppose the original reference group is North. Then b₂ may compare South with North.
If South becomes the reference category, a new coefficient may instead compare North with South.
The fitted predictions remain the same because the model has simply been reparameterized.
This illustrates an important point: individual regression coefficients depend partly on how variables are coded, while the underlying fitted relationship can remain unchanged.
Interaction Terms
Multiple regression can represent situations in which the relationship between one predictor and Y depends on another predictor.
Consider:
ŷ = b₀ + b₁x₁ + b₂x₂ + b₃x₁x₂
The interaction term is:
b₃x₁x₂
The effect of x₁ on the fitted outcome is now:
Change in ŷ per unit of x₁ = b₁ + b₃x₂
Therefore, there is no single universal slope for x₁. Its fitted relationship with Y changes according to the value of x₂.
Similarly, the relationship associated with x₂ depends on x₁.
When interactions are present, interpreting b₁ or b₂ alone as though each represented an unconditional overall effect can be misleading.
Nonlinear Relationships Within Multiple Regression
The word linear in multiple linear regression refers primarily to linearity in the coefficients, not necessarily to requiring every predictor to appear only in its original first-power form.
A model can include:
x
x²
x³
or other transformed predictors.
For example:
ŷ = b₀ + b₁x + b₂x²
is still linear in the coefficients b₀, b₁, and b₂ even though the fitted relationship between x and y is curved.
Logarithmic transformations, splines, and carefully chosen interaction terms can also extend the model’s functional form.
The key requirement is that the specified representation reasonably captures the structure needed for the analysis.
R² in Multiple Regression
R² summarizes how much of the observed variation in the response is represented by the fitted regression relative to a mean-only baseline in the standard OLS setting.
Its common formula is:
R² = 1 − SSE / SST
where:
SSE = Σ(yᵢ − ŷᵢ)²
and:
SST = Σ(yᵢ − ȳ)²
Suppose:
SSE = 250
and:
SST = 1,000
Then:
R² = 1 − 250/1,000
R² = 0.75
The fitted model accounts for 75% of the observed variation in Y relative to the mean-only baseline.
An R² of 0.75 does not mean that 75% of observations are predicted correctly, nor does it prove that the predictors cause 75% of the outcome.
Adding Predictors and R²
When ordinary least squares models are fitted to the same observations, adding another predictor cannot reduce the conventional training R².
The expanded model can always reproduce the smaller model by assigning the new predictor a coefficient of zero. Therefore its minimized SSE cannot be larger.
Conceptually:
R²expanded ≥ R²reduced
This creates a limitation. A predictor can increase R² slightly even when it contributes little stable information.
Therefore, choosing a model simply by maximizing training R² can favor unnecessary complexity and overfitting.
Adjusted R²
Adjusted R² modifies R² to account for the number of predictors in relation to the sample size.
A common formula is:
Adjusted R² = 1 − [(1 − R²)(n − 1) / (n − k − 1)]
where:
- n = sample size
- k = number of predictors
Suppose:
R² = 0.80
n = 100
k = 5
Then:
Adjusted R² = 1 − [(0.20 × 99) / 94]
Adjusted R² = 1 − 19.8/94
Adjusted R² ≈ 0.789
Unlike ordinary training R², adjusted R² can decrease after an unhelpful predictor is added.
It is useful for some comparisons among related linear regression models, but it is not a substitute for model validation, residual analysis, or substantive judgment.
The Null Hypothesis for a Regression Coefficient
Inference for an individual predictor commonly begins with a null hypothesis such as:
H₀: βⱼ = 0
A two-sided alternative is:
H₁: βⱼ ≠ 0
The null states that the predictor has zero conditional linear coefficient in the population model under the stated specification.
A test of βⱼ = 0 should not be interpreted as asking whether the predictor has absolutely no relationship with the outcome under every possible model. A variable can have nonlinear associations, interaction effects, or relationships obscured by model misspecification.
The test applies to the coefficient and model actually specified.
Testing an Individual Regression Coefficient
A common t statistic for a regression coefficient is:
t = (bⱼ − βⱼ,₀) / SE(bⱼ)
When testing:
H₀: βⱼ = 0
this becomes:
t = bⱼ / SE(bⱼ)
Suppose:
bⱼ = 4.0
and:
SE(bⱼ) = 1.5
Then:
t = 4.0 / 1.5
t ≈ 2.67
The statistic is interpreted using the appropriate t reference distribution under the regression assumptions.
A critical value can define the rejection boundary, or the equivalent p-value approach can be used.
The coefficient magnitude and its statistical significance remain different concepts. A large coefficient can be imprecise, while a small coefficient can be estimated very precisely.
Connection With the One-Sample T-Test
The coefficient t statistic and the one-sample t-test both use the broader logic of comparing an estimate with a hypothesized value relative to its standard error.
However, their estimands and model structures are different.
A one-sample t-test typically evaluates a population mean against a specified reference value. A regression coefficient test evaluates a conditional regression parameter within a fitted model.
The mathematical resemblance should therefore not blur their separate statistical questions.
Confidence Interval for a Regression Coefficient
A confidence interval for a coefficient commonly has the form:
bⱼ ± t* × SE(bⱼ)
where t* is the relevant critical value for the chosen confidence level and degrees of freedom.
Suppose:
bⱼ = 4.0
SE(bⱼ) = 1.5
and:
t* = 2.0
Then:
Margin of error = 2.0 × 1.5 = 3.0
giving:
4.0 ± 3.0
or:
1.0 to 7.0
The interval communicates the precision of the estimated coefficient under the model assumptions.
It should not be interpreted as assigning a 95% posterior probability to the fixed population coefficient when the interval is a conventional frequentist 95% confidence interval.
Overall Regression Test
A multiple regression analysis can also test whether the predictors collectively provide explanatory information beyond an intercept-only model.
A common null hypothesis is:
H₀: β₁ = β₂ = … = βₖ = 0
The alternative is that at least one slope coefficient differs from zero.
An F statistic can compare explained and unexplained variation while accounting for degrees of freedom.
The general structure is:
F = MSR / MSE
where MSR is the regression mean square and MSE is the residual mean square.
A significant overall test indicates evidence that the complete set of predictors improves the linear model relative to the intercept-only specification. It does not establish that every individual predictor is important.
Individual Tests vs Overall Model Test
It is possible for the overall regression to be statistically significant while some individual coefficients are not.
This can happen because several predictors jointly contain useful information even though uncertainty about a particular coefficient is substantial.
Strong correlations among predictors can also make individual coefficient estimates imprecise while the model as a whole predicts Y well.
Conversely, attention should not focus solely on whether each coefficient crosses a significance threshold. Model purpose, magnitude, uncertainty, and predictive performance should also be considered.
Hypothesis testing is one component of regression interpretation rather than the entire analysis.
Multicollinearity
Multicollinearity occurs when predictors contain strongly overlapping linear information.
Suppose x₁ and x₂ are almost perfectly correlated. The data may clearly show that some combination of the two predicts Y, but it can be difficult to determine how much of the association should be assigned to b₁ versus b₂.
Consequences can include:
- large coefficient standard errors
- unstable coefficient estimates
- unexpected signs
- strong sensitivity to small changes in the dataset
- individually nonsignificant coefficients despite useful overall fit
Multicollinearity does not necessarily make predictions poor. It primarily creates difficulty in separating individual predictor contributions.
Why Coefficients Change When Predictors Are Added
Suppose a simple model contains only x₁:
ŷ = b₀ + b₁x₁
Then a second related predictor x₂ is added:
ŷ = b₀ + b₁x₁ + b₂x₂
The estimated b₁ can change because its interpretation has changed.
In the first model, b₁ reflects the relationship between x₁ and Y without adjustment for x₂. In the second, it reflects the relationship between x₁ and Y conditional on x₂.
If x₁ and x₂ are associated with one another and both relate to Y, this distinction can be substantial.
A coefficient therefore belongs to a model specification. It should not be interpreted independently of the other variables included.
Linearity Assumption
The standard multiple linear regression model assumes that the conditional mean of Y is represented adequately by the specified linear predictor.
This does not mean every raw relationship must look like a perfectly straight line. Transformations and polynomial terms can be included when appropriate.
What matters is whether the fitted functional form captures the systematic relationship sufficiently for the intended inference or prediction.
If residuals display strong curvature, the model may be missing nonlinear structure.
Adding more observations does not automatically fix an incorrect functional form.
Constant Variance
A standard OLS inference framework often assumes that the conditional variance of the error is constant:
Var(ε | X) = σ²
This is known as homoscedasticity.
If residual variability changes systematically with predictor values or fitted values, the data are heteroscedastic.
For example, prediction errors might be relatively small for low-income observations but much larger for high-income observations.
OLS coefficient estimates can still have useful properties under some forms of heteroscedasticity, but conventional standard errors and inference may become unreliable. Appropriate heteroscedasticity-robust methods or a better model specification may be needed.
Independence
Ordinary regression inference typically assumes observations provide appropriately independent information conditional on the model.
This assumption can fail with:
- repeated measurements from the same person
- students clustered within schools
- patients within hospitals
- geographic clustering
- time-series observations
- network-related data
Ignoring dependence can make conventional standard errors too small or otherwise misleading.
Large sample size alone does not repair an incorrect independence assumption. The model or inferential procedure must reflect the structure that generated the observations.
Normality of Errors
Normality is not required simply to calculate ordinary least squares coefficient estimates.
However, exact small-sample t and F inference under the classical model is associated with assumptions about normally distributed errors conditional on the predictors.
With sufficiently well-behaved large samples, some inferential methods can rely on asymptotic approximations even when errors are not exactly normal.
Severe skewness, heavy tails, or influential outliers can still cause problems, especially in small samples.
Normality should therefore be viewed in relation to the inferential method rather than as a rule that every predictor or outcome must itself have a normal marginal distribution.
Predictors Do Not Have to Be Normally Distributed
Multiple regression does not generally require:
X₁ ∼ Normal
X₂ ∼ Normal
and so on.
A predictor can be skewed, binary, categorical, or otherwise non-normal.
What matters is whether the regression specification correctly represents how the conditional outcome relates to the predictors and whether the assumptions required for the intended inference are sufficiently satisfied.
This distinction is important because analysts sometimes apply unnecessary transformations solely to make predictor histograms appear normal.
Predictor normality is not a general OLS requirement.
Outliers and Influential Observations
An outlier has an unusual response relative to the fitted model, while a high-leverage observation has unusual predictor values. An observation can be influential when removing or modifying it would substantially change the fitted regression.
These concepts overlap but are not identical.
An extreme residual may have limited influence if its predictor values are ordinary. A high-leverage observation may lie close to the fitted regression surface and therefore have a modest residual while still strongly determining the fitted coefficients.
Regression diagnostics should therefore consider several aspects of unusual observations rather than using residual size alone.
Genuine observations should not be deleted merely because they weaken a desired result.
Overfitting
Overfitting occurs when a model captures patterns specific to the observed sample that do not generalize well to new observations.
Multiple regression becomes more vulnerable to overfitting when the number of predictors is large relative to the available information, when many transformations and interactions are tested, or when model selection repeatedly searches the same data for favorable specifications.
Training R² usually increases with additional predictors, so excellent in-sample fit does not protect against overfitting.
For predictive applications, model performance should be evaluated on genuinely unused data or with an appropriate resampling strategy.
Extrapolation
Regression predictions are usually safest within the range and structure of predictor values represented in the data used to fit the model.
Suppose a relationship is estimated using x values between:
10 and 50
Predicting at:
x = 500
requires assuming that the fitted relationship continues far beyond the observed evidence.
Even a model with high R² within the sample can extrapolate poorly.
Interactions, nonlinear relationships, physical constraints, and structural changes can all make out-of-range predictions especially unreliable.
A regression equation is not automatically a universal law.
Multiple Regression and Effect Size
Regression coefficients themselves can function as effect size estimates when their units are meaningful.
Suppose:
b₁ = 5.2
If x₁ represents one additional hour of training and Y represents performance points, the coefficient describes an estimated 5.2-point conditional difference per additional hour.
Standardized regression coefficients can also be calculated when comparison across differently scaled predictors is useful, but they remove the original units and should not automatically replace unstandardized coefficients.
The most useful effect measure depends on the substantive question.
A statistically significant coefficient can still correspond to a practically tiny effect, while an important estimated effect can remain uncertain in a small sample.
Standardized Regression Coefficients
If variables are standardized before fitting a linear regression, the resulting slope coefficients can be expressed in standard-deviation units.
A standardized predictor typically has:
mean = 0
standard deviation = 1
A standardized coefficient can then describe how many standard deviations the predicted response changes for a one-standard-deviation increase in the predictor, holding other included predictors constant.
These coefficients can make scales more comparable, but larger absolute standardized coefficients do not always imply greater causal or practical importance.
Correlated predictors, measurement reliability, functional form, and model specification can all affect the coefficients.
Multiple Regression vs Logistic Regression
Both models can contain several predictors, but their response variables and mathematical structures differ.
Standard multiple linear regression models a quantitative outcome:
ŷ = b₀ + b₁x₁ + … + bₖxₖ
Binary logistic regression instead models the log-odds of a binary outcome:
log[p / (1 − p)] = β₀ + β₁x₁ + … + βₖxₖ
Linear regression coefficients describe changes on the original response scale. Logistic coefficients describe changes in log-odds and are often exponentiated to obtain odds ratios.
The models should therefore not be selected merely because both can contain multiple predictors. The outcome structure is fundamental.
Multiple Regression Does Not Prove Causation
Suppose a fitted regression estimates a positive coefficient between advertising and sales after several observed predictors are included.
That conditional relationship may be consistent with a causal advertising effect, but the regression coefficient alone does not prove it.
Possible alternative explanations include:
- unmeasured confounding
- reverse causation
- selection effects
- omitted variables
- measurement error
- incorrect functional form
For example, businesses expecting unusually high future demand may deliberately increase advertising. The positive coefficient could then partly reflect expected demand influencing advertising rather than advertising alone influencing sales.
Causal interpretation requires a defensible research design and additional assumptions beyond fitting a multiple regression equation.
Prediction vs Explanation
A regression model can be useful for prediction without providing a simple causal explanation.
A predictive model may include variables because they improve forecasts even if their coefficients have no causal meaning.
Conversely, an explanatory analysis may care strongly about one coefficient even if the complete model’s prediction error remains substantial.
These objectives can lead to different modeling choices.
For prediction, out-of-sample accuracy and stability may dominate. For parameter interpretation, identification assumptions, model specification, uncertainty, and meaningful coefficient definitions may matter more.
The intended goal should therefore be clear before model performance is judged.
Common Misconceptions
One common misconception is that a regression coefficient shows how much Y will change if a predictor is deliberately changed. Without a causal design, it only describes the fitted conditional relationship.
Another mistake is interpreting “holding other variables constant” as meaning all possible confounders have been controlled. It refers only to the predictors represented in the fitted model.
A third error is assuming high R² guarantees a good model. A model can fit the sample well while containing serious functional-form problems, influential observations, data leakage, or poor out-of-sample performance.
It is also incorrect to assume predictors must be normally distributed. That is not a general multiple regression requirement.
Another misconception is that adding more predictors always improves the model. Training fit cannot deteriorate under ordinary nested OLS, but unnecessary predictors can increase complexity, instability, and overfitting.
Finally, statistical significance should not be confused with practical importance. A coefficient can be precisely estimated yet too small to matter in the actual application.
Practical Multiple Regression Workflow
Begin by clearly defining the quantitative outcome and the predictors relevant to the research question. Determine whether each predictor is continuous, categorical, or requires a transformation, and decide whether interactions or nonlinear terms have substantive justification.
Fit the specified model:
ŷ = b₀ + b₁x₁ + … + bₖxₖ
Then evaluate coefficient estimates in their correct conditional context. Examine their standard errors and confidence intervals if inference is required.
Assess model fit, but do not rely on R² alone. Examine residuals, influential observations, functional form, heteroscedasticity, dependence, and multicollinearity.
For predictive use, evaluate performance outside the fitting sample whenever possible.
Finally, interpret the results according to the original purpose. Keep prediction separate from causal explanation and keep statistical significance separate from effect magnitude.
How to Report a Multiple Regression Result
A useful report should state what outcome was modeled, which predictors were included, how coefficients are interpreted, and the relevant uncertainty.
Suppose a fitted coefficient is:
b₁ = 3.4
with a 95% confidence interval of:
1.2 to 5.6
A contextual report might state that, holding the other included predictors constant, a one-unit increase in x₁ was associated with an estimated 3.4-unit increase in Y, with the corresponding confidence interval spanning 1.2 to 5.6 units.
If the complete model has:
R² = 0.62
that information can be reported separately as a measure of overall in-sample fit.
This presentation keeps coefficient magnitude, uncertainty, and model fit conceptually distinct.
Frequently Asked Questions
What is multiple regression?
Multiple regression is a statistical method that models a quantitative outcome using two or more predictors simultaneously.
What is the multiple regression formula?
The standard fitted linear equation is:
ŷ = b₀ + b₁x₁ + b₂x₂ + … + bₖxₖ
where ŷ is the predicted response and the b values are estimated regression coefficients.
What does a coefficient mean?
A coefficient represents the estimated change in the response associated with a one-unit increase in its predictor while the other predictors included in the model are held constant.
What does the intercept mean?
The intercept is the fitted response when all numerical predictors equal zero and categorical predictors are at their reference categories. It may not be substantively meaningful if that predictor combination is unrealistic.
What is a residual?
A residual is:
eᵢ = yᵢ − ŷᵢ
It measures the difference between an observed response and its fitted value.
How does OLS estimate the coefficients?
Ordinary least squares chooses the coefficient values that minimize:
SSE = Σ(yᵢ − ŷᵢ)²
Can categorical variables be used?
Yes. Categorical predictors can be represented through indicator variables or another appropriate coding scheme.
Can multiple regression include nonlinear relationships?
Yes. Polynomial terms, transformations, interactions, and other specified basis functions can represent nonlinear patterns while maintaining a model linear in its coefficients.
Do predictors need to be normally distributed?
No. Predictor normality is not a general requirement of multiple linear regression.
What is multicollinearity?
Multicollinearity occurs when predictors contain strongly overlapping information. It can make individual coefficients unstable and increase their standard errors.
What does R² measure?
R² measures the reduction in squared residual variation relative to the total variation around the mean under the conventional OLS interpretation.
Does a high R² mean the model is good?
Not necessarily. High R² does not guarantee correct functional form, reliable inference, causal validity, or strong performance on new data.
Can adding a predictor lower R²?
Conventional training R² cannot decrease when another predictor is added to a nested OLS model fitted to the same observations. Adjusted R² can decrease.
What is adjusted R²?
Adjusted R² modifies ordinary R² to account for the number of predictors and sample size, penalizing added complexity that provides insufficient improvement in fit.
How is a regression coefficient tested?
A common statistic for testing H₀: βⱼ = 0 is:
t = bⱼ / SE(bⱼ)
The statistic is compared with an appropriate t reference distribution.
What is the difference between multiple regression and logistic regression?
Multiple linear regression ordinarily models a quantitative response. Binary logistic regression models the probability of a two-category outcome through log-odds.
Does multiple regression prove causation?
No. A regression coefficient is a conditional association unless the study design and additional assumptions justify a causal interpretation.
What is the difference between prediction and inference?
Prediction focuses on estimating unknown outcomes accurately, often on new observations. Inference focuses on estimating and reasoning about population parameters and their uncertainty.
Can regression coefficients change when another variable is added?
Yes. Each coefficient is conditional on the other predictors in the model, so changing the model specification can change its interpretation and estimate.
Should multiple regression be used only when every predictor is significant?
No. Predictor selection should follow the objective, design, substantive knowledge, model structure, and predictive or inferential requirements rather than a rule requiring every coefficient to cross a significance threshold.
Key Takeaway
Multiple regression models a quantitative response using several predictors:
ŷ = b₀ + b₁x₁ + b₂x₂ + … + bₖxₖ
Each slope coefficient describes the estimated conditional relationship between its predictor and the response while the other included predictors are held constant. Ordinary least squares commonly estimates the coefficients by minimizing:
SSE = Σ(yᵢ − ŷᵢ)²
The resulting model can support description, prediction, adjustment, and statistical inference, but its usefulness depends on more than the fitted equation. Functional form, residual variation, independence, multicollinearity, influential observations, uncertainty, overfitting, and extrapolation all affect interpretation. Most importantly, a regression coefficient is not automatically a causal effect, a statistically significant result is not automatically practically important, and a high R² is not automatically evidence of a valid model. Multiple regression is strongest when its conditional coefficients, assumptions, uncertainty, and intended purpose are interpreted together.



